2019 to 2021
Adding vision and sound to BERT
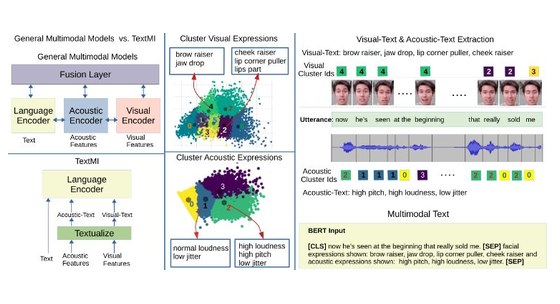
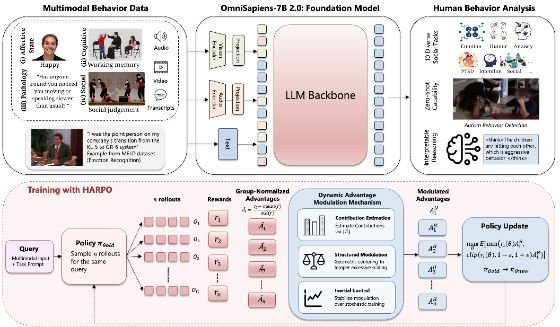
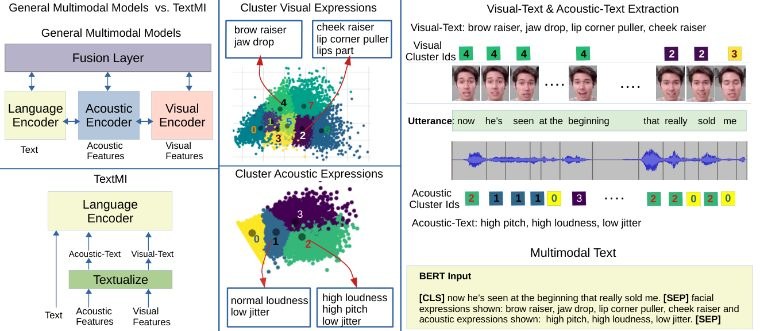
Pretrained language models such as BERT and XLNet had no way to take in a speaker's face or voice. Our Multimodal Adaptation Gate (MAG) adds them during fine-tuning by shifting the model's internal representation of each word according to the visual and acoustic cues around it. MAG-XLNet reached human-level performance on multimodal sentiment analysis for the first time. The same team built UR-FUNNY and a humor-aware transformer to teach these models to get jokes.
-
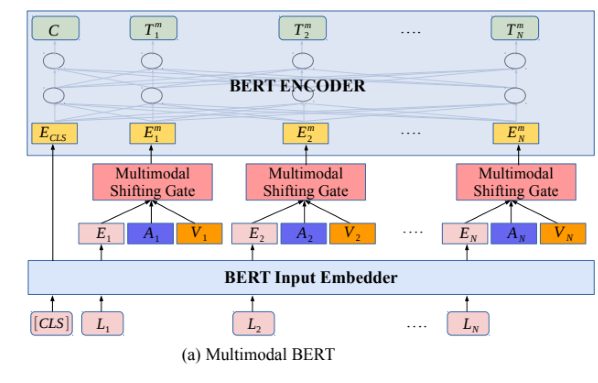 Integrating Multimodal Information in Large Pretrained Transformers
Lets BERT-style language models take in voice and facial cues, not only words, improving sentiment and behavior understanding.
-
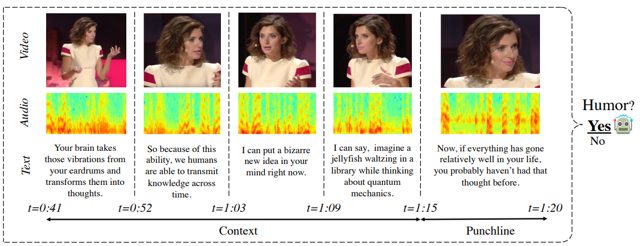 UR-FUNNY: A Multimodal Language Dataset for Understanding Humor
UR-FUNNY: a multimodal dataset of words, voice and gestures from TED talks for teaching AI to understand humor.
-
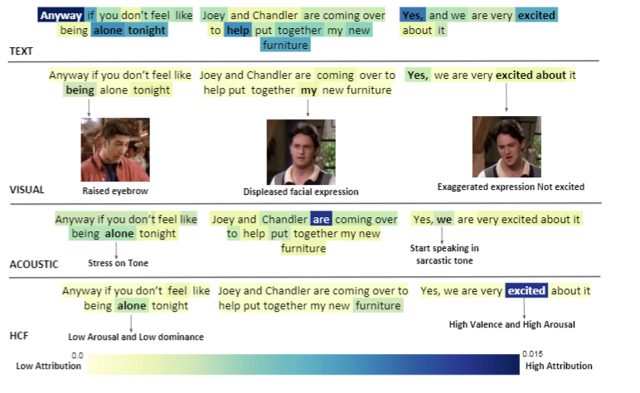 Humor Knowledge Enriched Transformer for Understanding Multimodal Humor
Teaching AI to get jokes: a transformer that combines words, voice and facial cues with external humor knowledge to recognize humor in video.